
Hello there, I’m
Jacob Smith

ABOUT ME
A technical professional with over a Decade of experience working across infrastructure, operations, and support. I’ve built a deep skillset in Automation, Kubernetes, Terraform, cloud‑native tooling, and modern reliability practices. I take ownership of complex systems, focus on clarity and stability, and enjoy turning messy environments into predictable, well‑instrumented platforms.
My Story so Far...

I graduated with a mathematics degree and jumped straight into the early days of Darktrace in 2015, joining when it was still a rising UK tech newcomer. I started as a jack‑of‑all‑trades sysadmin — fixing whatever needed fixing, learning fast, and getting my hands on every part of the stack.

I shifted from pure sysadmin work into customer support, then deeper into DevOps and Infrastructure. This was where I built real technical muscle — automation, systems thinking, and the foundations of modern operational engineering.

I was trusted early with high‑impact work, and in 2022 the company asked me to relocate to the US to take ownership of AMER corporate infrastructure — a move that reflected the confidence they had in my technical judgment and reliability.

As my skillset expanded, I moved into managing regional technical staff. I focused on clarity, calm decision‑making, and building trust across distributed teams. Leading engineers became as natural to me as supporting systems.

Alongside leadership, I’ve invested heavily in modern cloud‑native engineering — automation, observability, Kubernetes, and platform design. I’ve been practicing hands‑on by building out my portfolio, sharpening the skills that define my next chapter.
My Portfolio
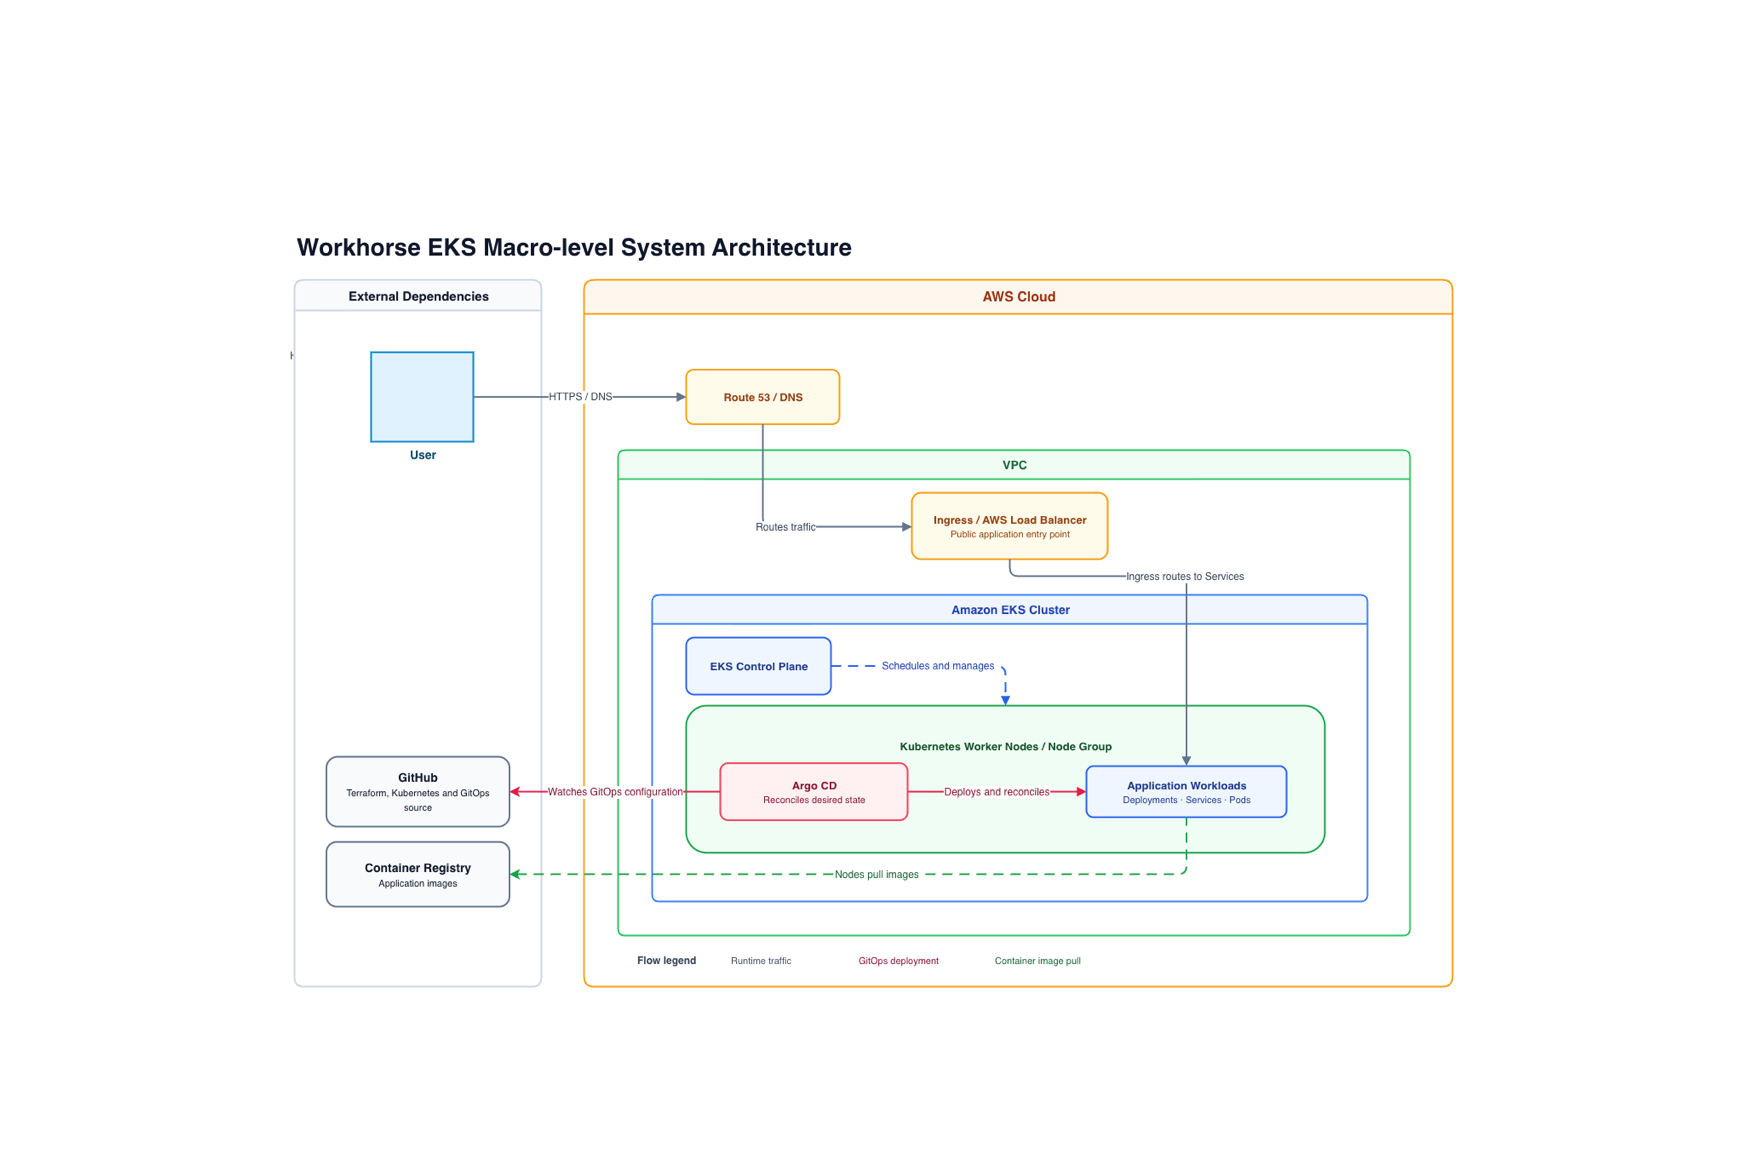
Alongside my day-to-day work, I've been building Workhorse — a hands-on platform engineering lab where I design, break, and fix cloud-native infrastructure the way a real Engineering team would.
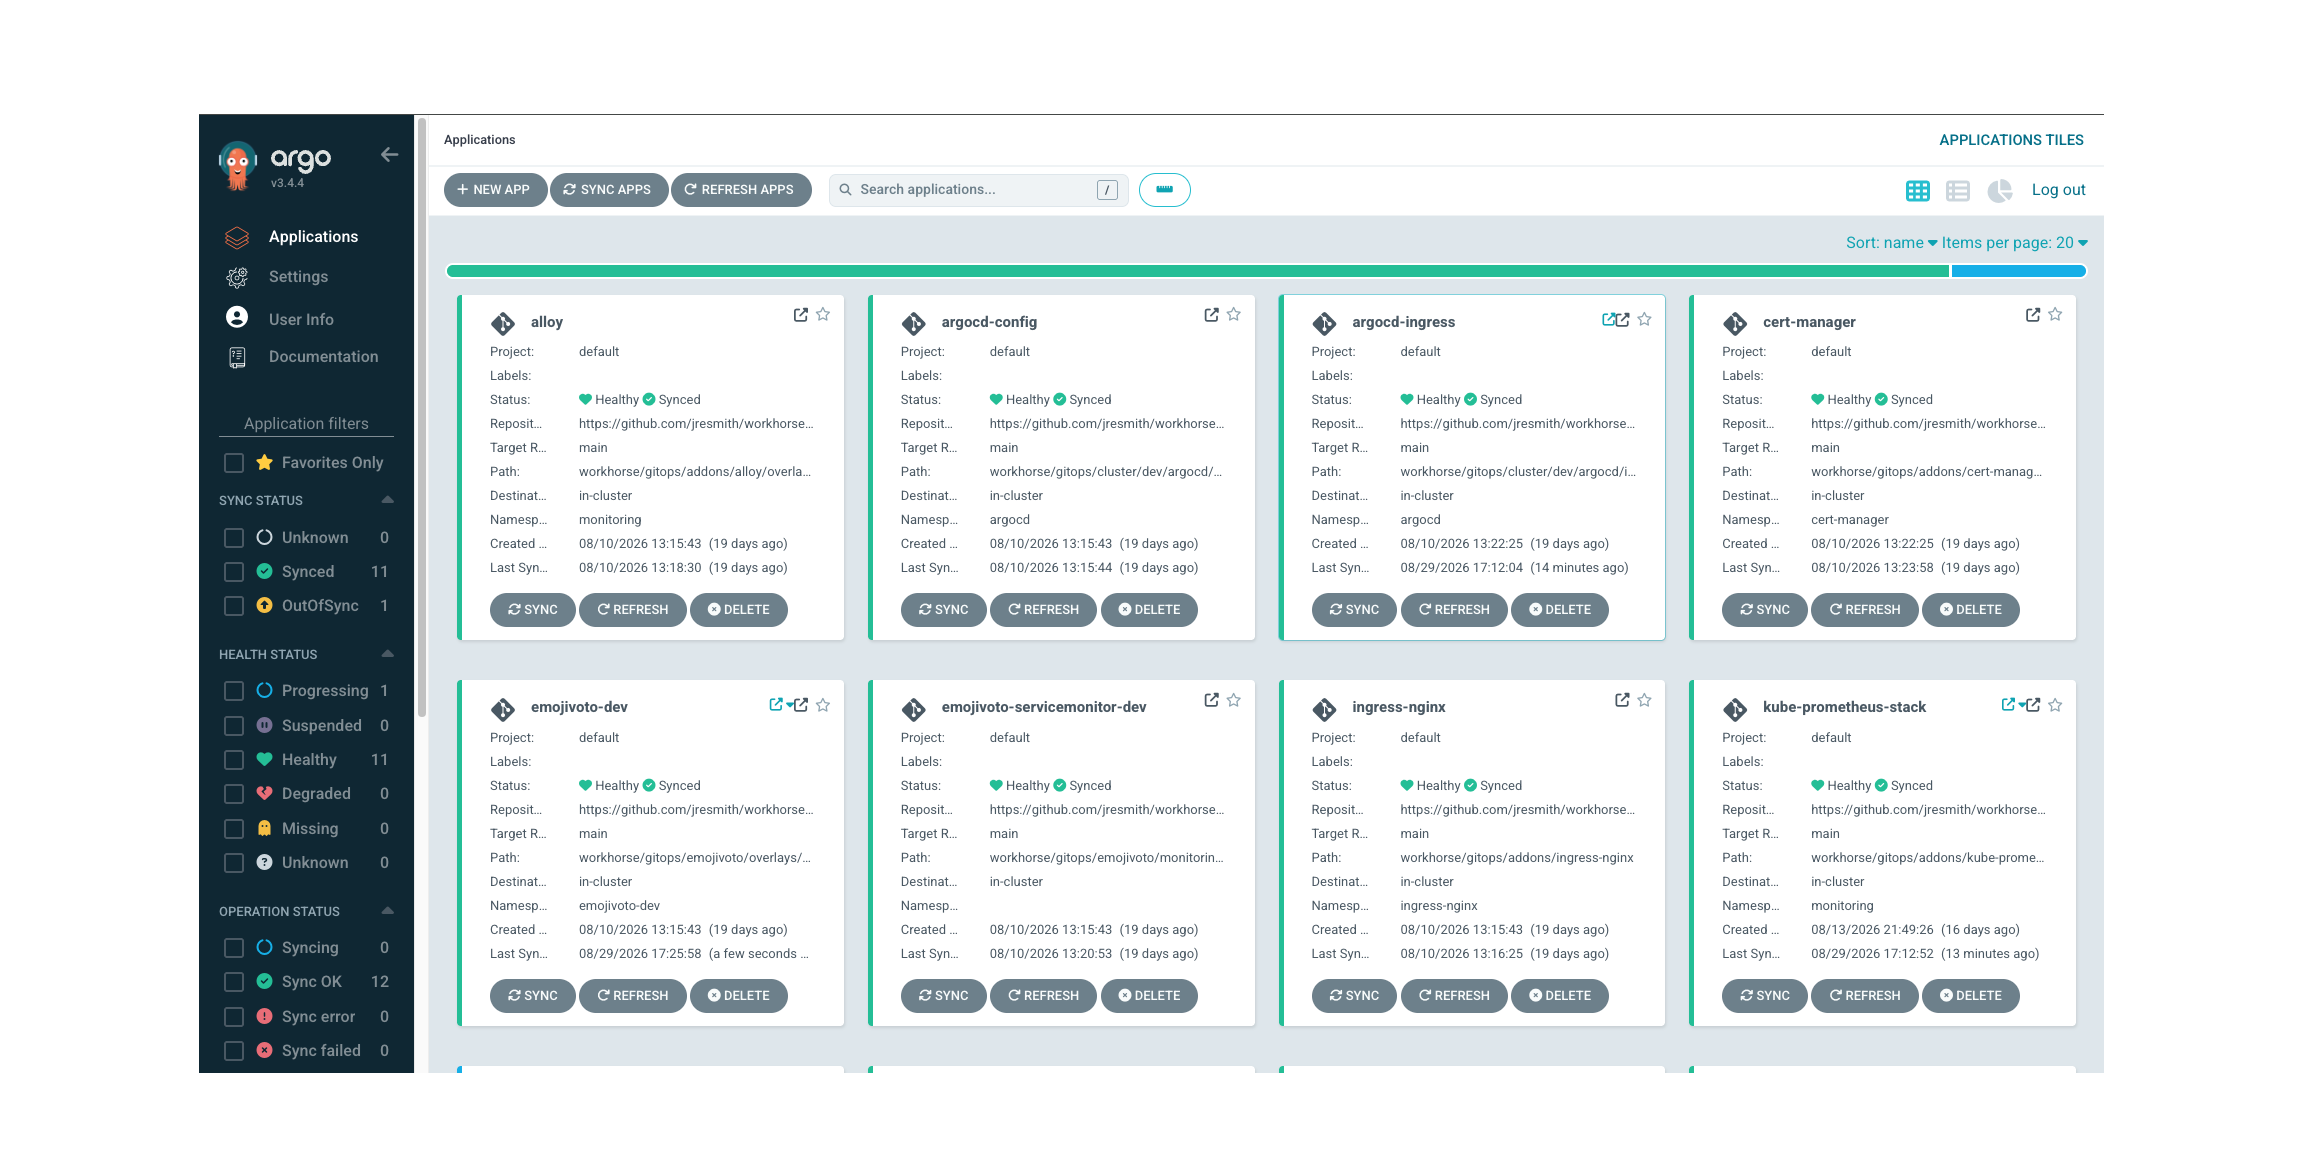
EKS + Terraform + ArgoCD, running as dev/staging/prod environments with full GitOps delivery
A real root-cause investigation, five-whys, and prevention plan for a logging pipeline outage — written the way I'd write one on a team
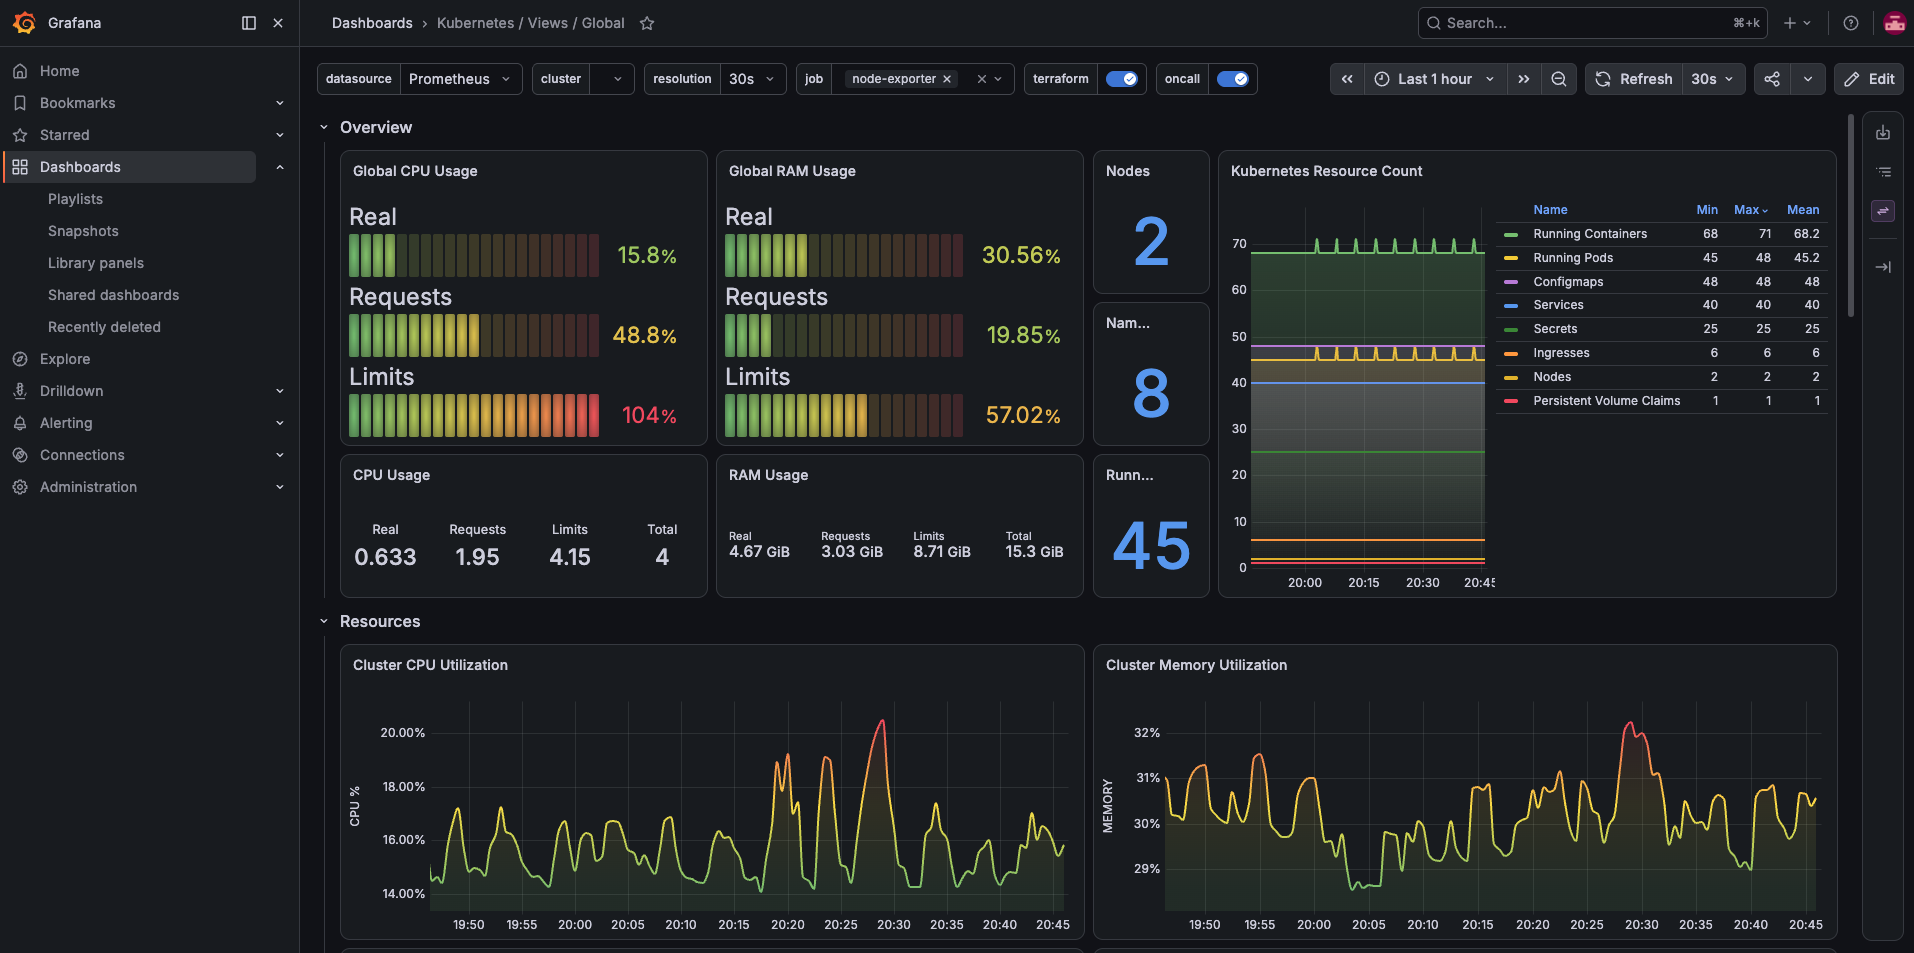
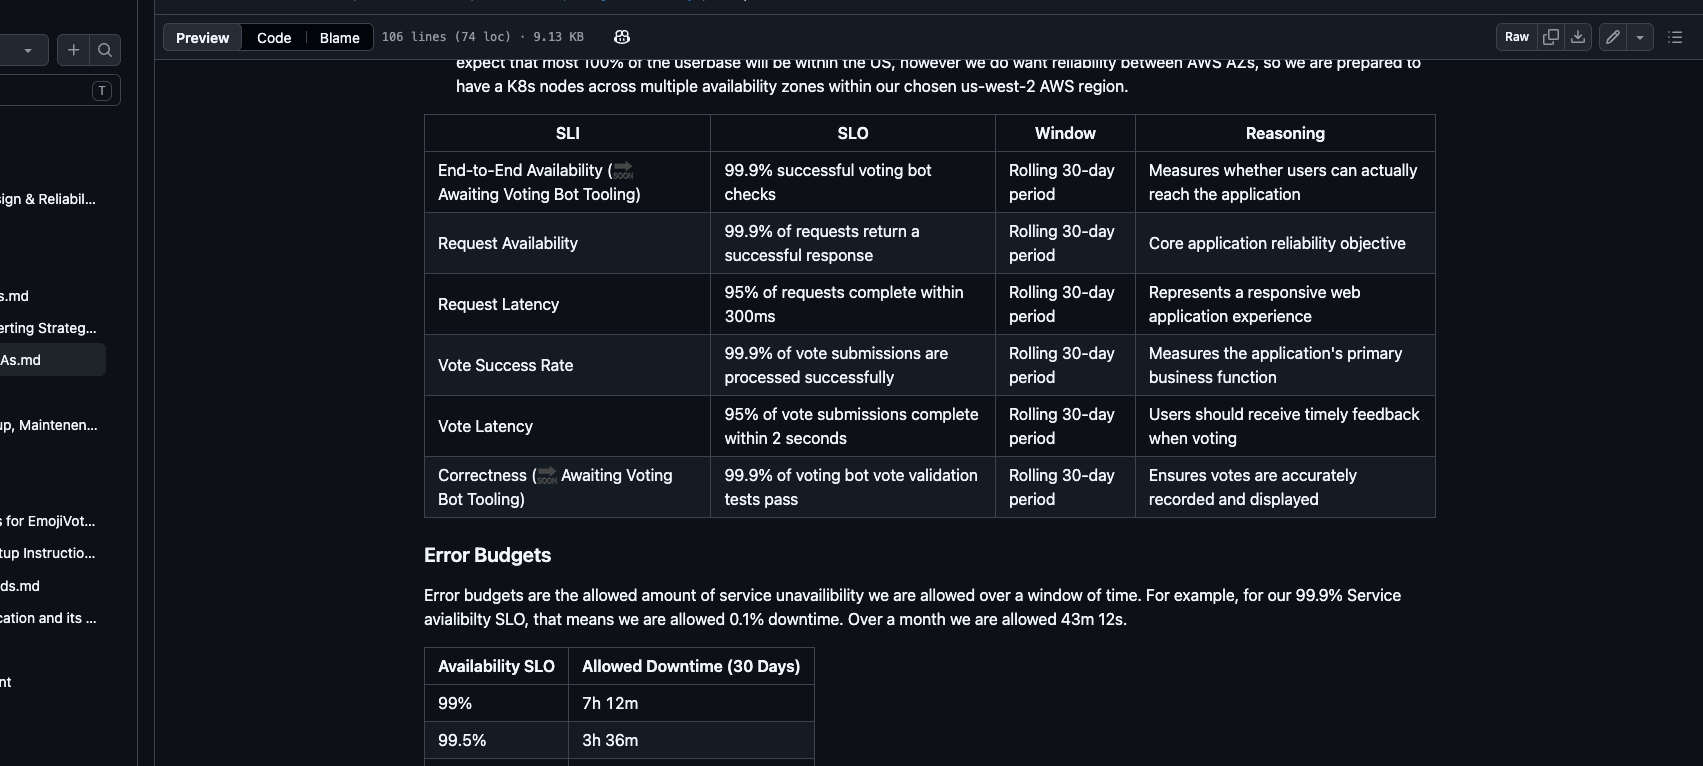
Multi-window, multi-burn-rate SLO alerting — the same pattern used in Google's SRE workbook — implemented in Prometheus
My Stack


What do I do?


